
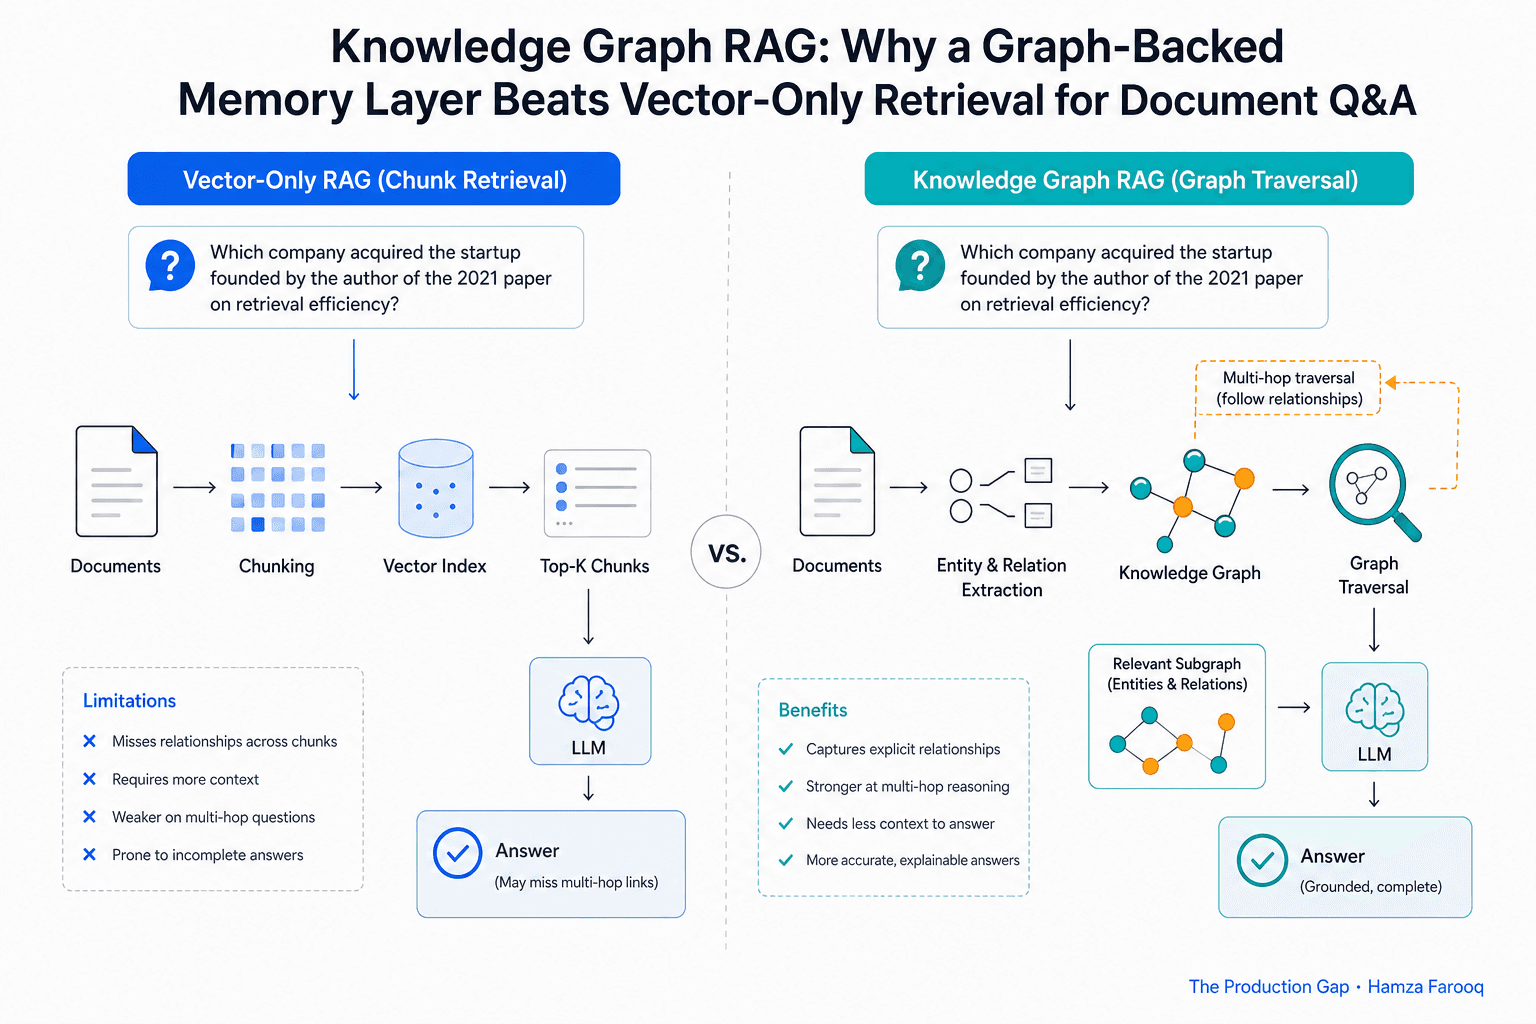
TL;DR: Knowledge graph RAG outperforms vector-only retrieval for document Q&A whenever answers depend on traversing relationships across multiple entities rather than matching semantically similar passages. A graph-backed memory layer preserves explicit connections between facts, letting the system follow chains of reasoning that embedding search routinely misses. Vector-only retrieval remains the right call when queries are self-contained and relationship traversal adds no meaningful value.
Key Takeaways
- Graph RAG wins on relationship queries: A knowledge graph finds multi-hop answers in fewer steps than similarity scanning alone.
- Vector-only RAG still earns its place: For single-passage factual lookups, a vector store is cheaper, faster, and simpler.
- A durable harness keeps the graph honest: Without continuous sync, the graph drifts and quietly returns wrong answers.
- Microsoft GraphRAG changed the approach: Pre-computed community summaries let agents answer broad analytical questions that standard chunk retrieval struggles to address.
- Document graph memory is not episodic memory: One captures what your corpus says; the other captures what a user has done over time.
- Graph traversal retrieves only connected facts: This keeps cost and hallucination risk lower than stuffing a large context window with loosely relevant content.
Introduction
Most teams shipping document Q&A hit the same wall: vector RAG handles simple lookups but falls apart on questions requiring facts connected across multiple documents. The KG²RAG paper formalizes graph-guided retrieval as a studied architecture, which means teams now need rigorous criteria, not enthusiasm. This article makes the precise case for graph RAG, gives you a decision framework for when it is overkill, and confronts the maintenance debt that kills most production projects.
Why does vector-only RAG fail on multi-hop and relationship queries?
Vector-only RAG fails multi-hop queries because similarity search retrieves chunks semantically close to the question, not chunks logically connected to each other, so facts spread across separate documents never get linked.
Consider: "Which vendor supplies the component used in the product flagged in the Q3 audit?" That requires traversing four fact nodes: vendor, component, product, and audit flag. None of them are guaranteed to live in a single chunk. Three failure modes tend to emerge: (1) context window stuffing, where tangentially similar chunks dilute relevant signal; (2) multi-hop hallucination, where the model fabricates connections rather than admitting it cannot find them; (3) ranking collapse, where two contradictory chunks arrive with equal similarity scores and no structure to arbitrate between them.
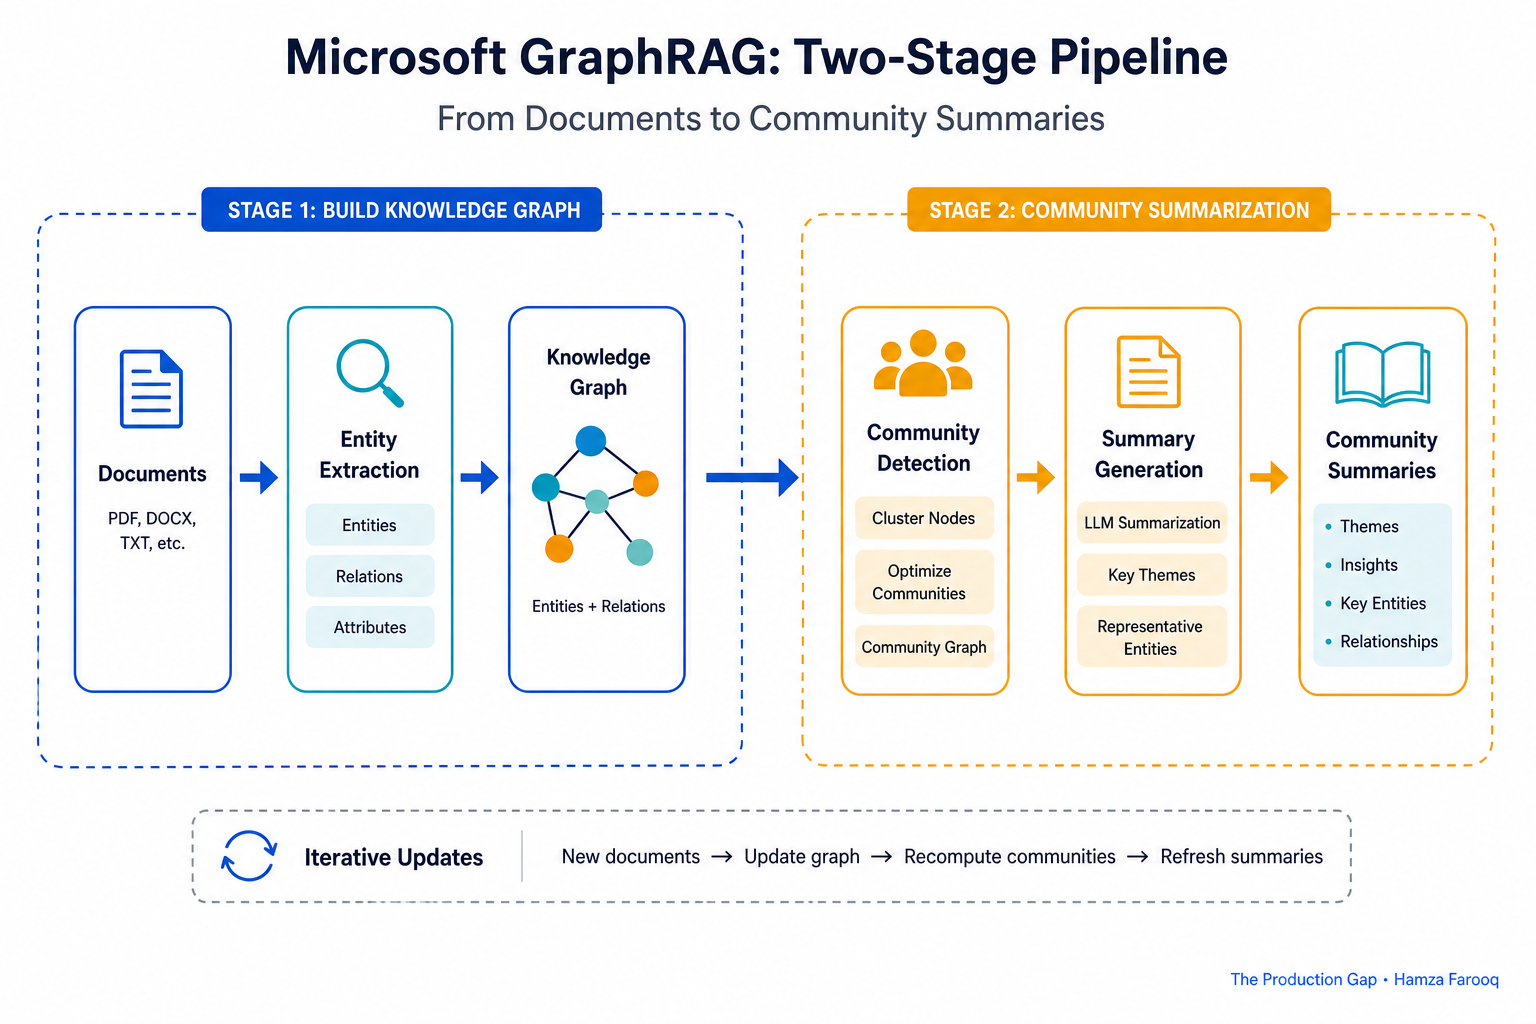
How does Microsoft GraphRAG's community-summary architecture solve this, and what does it cost?
Microsoft GraphRAG addresses multi-hop retrieval by building a knowledge graph from the corpus and pre-computing community summaries so broad analytical questions are answered by retrieving a summary rather than scanning individual passages.
| Dimension | Microsoft GraphRAG | Custom KG Harness (Neo4j + LangChain) |
|---|---|---|
| Setup effort | Low (reference pipeline) | High, schema design required |
| Community summaries | Built-in | Manual or custom |
| Sync on doc update | Rebuild index | Event-driven harness |
| Traversal control | Limited | Full Cypher control |
| Best fit | Analytical Q&A, stable corpora | Live corpora, complex schemas |
Why is a durable synchronization harness the real argument for graph RAG?
A knowledge graph that is not continuously synchronized with its source documents becomes a stale liability, returning confidently wrong answers that a vector store, refreshed by re-embedding, would have avoided.
A concrete failure pattern: a vendor contract updates, the vector store re-embeds automatically, but the graph still holds the old relationship. Because structured graph data carries implicit authority, it can override the fresher vector result and deliver a wrong answer with high confidence. That outcome is worse than a vector store's honest uncertainty. In the author's synthesis of production patterns, corpus maintenance is the central operational concern for any team running graph RAG at scale, not retrieval quality.
The Durable Harness Pattern
- Document Ingest Watcher: Monitors the corpus for creates, updates, and deletes and emits a change event for every modification.
- Differential Extractor: Re-runs entity and relationship extraction only on changed documents, avoiding a full index rebuild on every update.
- Graph Reconciler: Diffs new extractions against existing nodes and edges, then applies targeted updates rather than overwriting the full graph.
- Staleness Monitor: Flags nodes whose source documents have not been confirmed fresh within a configurable TTL, surfacing drift before it reaches users.
This pattern is a practical rule of thumb synthesized from common failure modes, not a specification from an external standard. Teams that skip any one component typically discover the gap when a confident wrong answer reaches a user.
When should you use graph RAG, and how is this different from episodic graph memory?
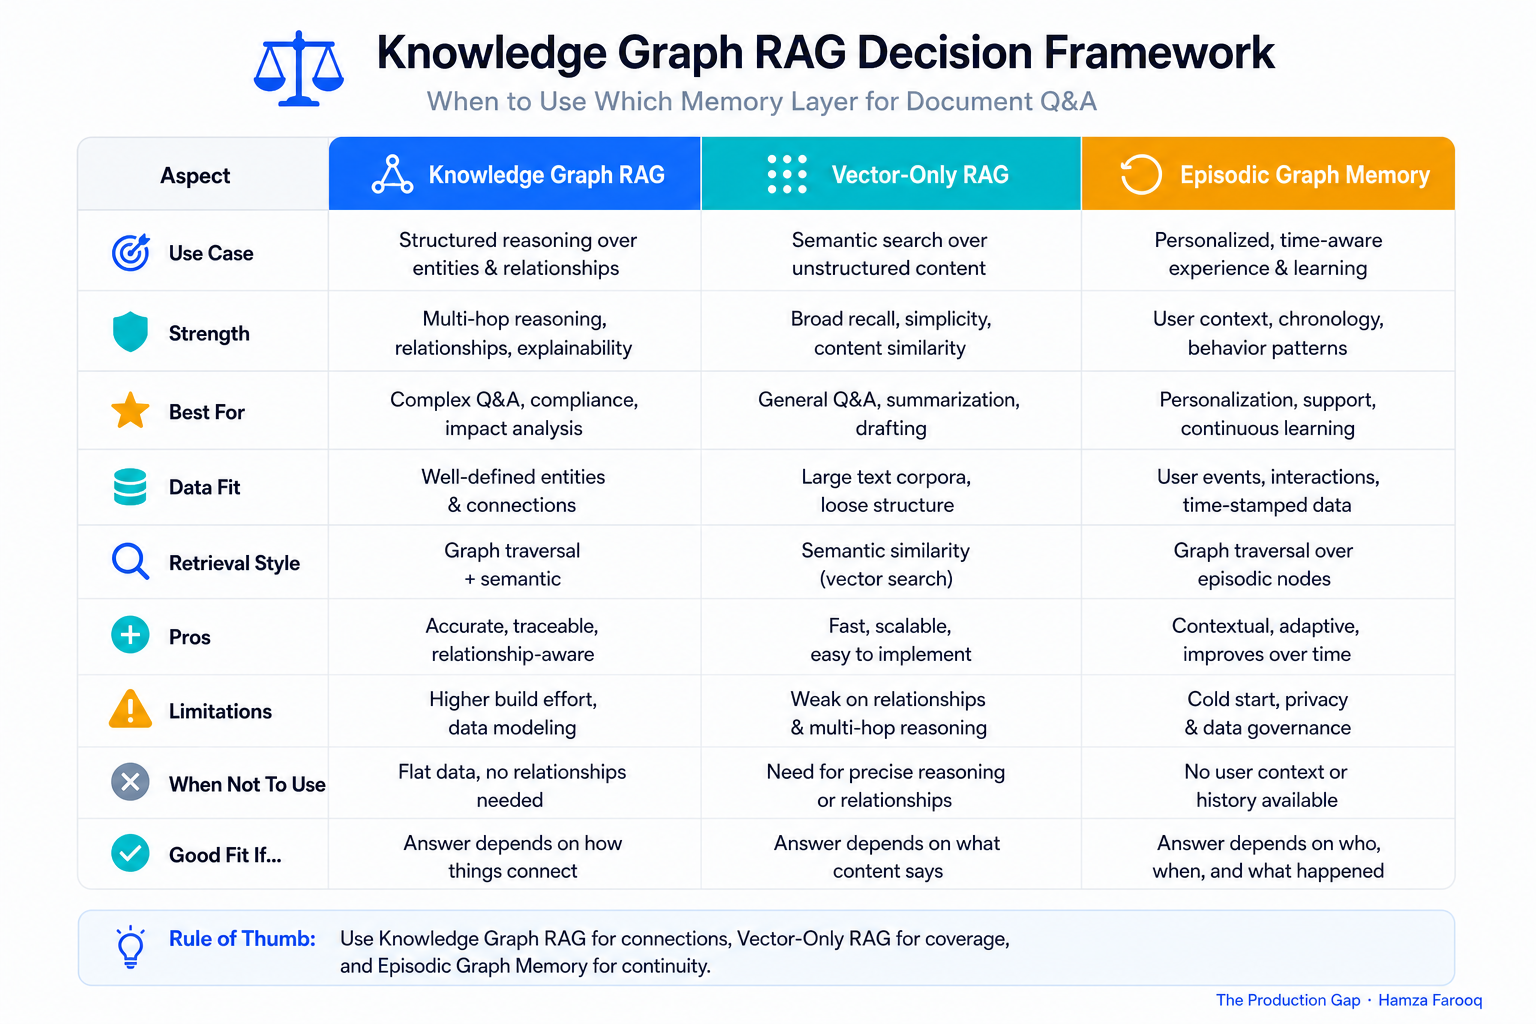
Use knowledge graph RAG when queries require connecting facts across multiple documents; skip it when a single retrieved passage suffices; and do not confuse it with episodic graph memory, which tracks behavioral patterns over time rather than document content.
The table below maps six common deployment signals to a graph RAG verdict and rationale.
| Signal | Verdict | Reason |
|---|---|---|
| Queries require multi-hop reasoning | Use graph RAG | Vector similarity cannot traverse logical chains |
| Simple factual lookups dominate | Skip graph RAG | Vector store is faster, cheaper, and sufficient |
| Corpus changes frequently | Only with durable harness | Without sync, the graph becomes a liability |
| Large, stable corpus (e.g., legal archive) | Strong fit | Community summaries reward stable corpora |
| Analytical queries across many documents | Use community summaries | GraphRAG excels here |
| Limited budget or team bandwidth | Start with vectors | Graph RAG carries real operational overhead |
Document graph RAG captures what your corpus says: entities, facts, and relationships extracted from documents. Episodic graph memory captures what a user or agent has done: action sequences logged for personalization or continuity. Building a document Q&A system on an episodic architecture, or the reverse, fails in both directions.
Frequently Asked Questions
When does knowledge graph RAG outperform vector-only retrieval? When a question requires connecting facts across multiple documents, such as tracing a defect from supplier to component to audit report, graph traversal follows logical chains that vector search cannot replicate.
How do you keep a knowledge graph synchronized with a changing corpus? Build a durable harness: every document change triggers differential extraction, graph reconciliation, and staleness flagging. Without it, stale structured data overrides conflicting vector signals with unearned confidence.
What is the difference between document graph RAG and episodic graph memory? Document graph RAG captures what a corpus says. Episodic graph memory captures what a user or agent has done over time. They serve different purposes and are not interchangeable.
Do large context windows make graph RAG obsolete? No. Graph traversal retrieves only the connected subgraph relevant to a query. Stuffing a large context window with loosely relevant content spreads attention across material that does not contribute to the answer, which increases cost without a guaranteed accuracy gain. Graph RAG remains the more targeted approach for relational queries.
Conclusion
The architecture succeeds or fails in operations, not in design. A knowledge graph built once and left alone will confidently mislead your LLM within weeks of the first document update. The Durable Harness pattern described in this guide is not an implementation detail; it is the product.
If your queries are relational and multi-hop, and your team will actually operate the synchronization layer, graph RAG will outperform vector-only retrieval in ways users notice. If your queries are simple lookups and your team is stretched thin, vector RAG is the right call.
Audit the five hardest queries your vector RAG system fails on today. If three or more require connecting facts across documents, you have your business case, and now you have the architecture to support it.
Learn from me
Agent Engineering Bootcamp: Developers Edition, my Maven cohort. Advanced agentic RAG, multi-agent orchestration, memory, evals, and guardrails. Take agents from prototype to production. Join the next cohort →
Hire us
Traversaal.ai. We're a team of forward deployed engineers solving the toughest AI problems for Fortune 100 companies: document intelligence, agentic data platforms, and real-time web intelligence, deployed in production. Work with our team to deploy your next agentic ecosystem. Talk to Traversaal.ai →
Join us
Want to solve these problems with us? We're always looking for forward deployed engineers who want to ship production AI. jobs@traversaal.ai
